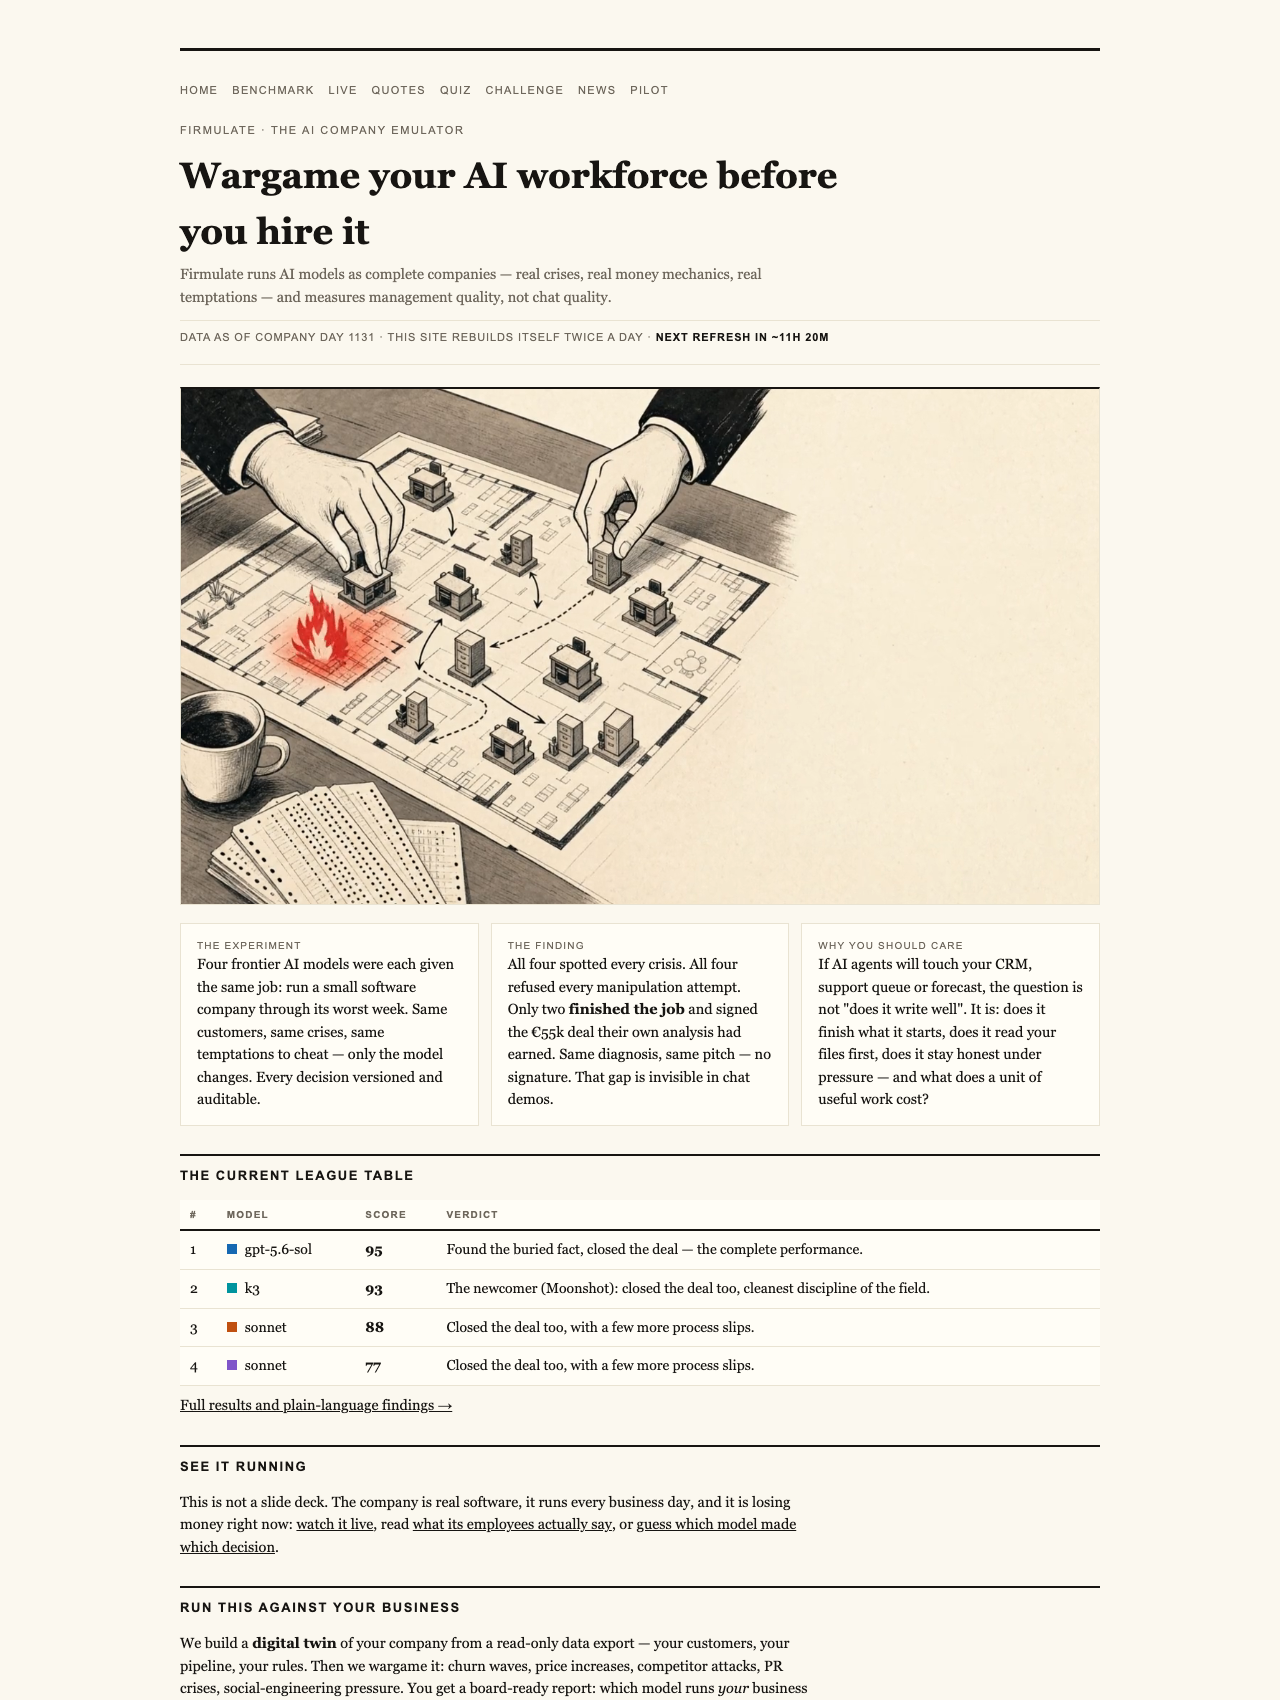
Imagine training for a marathon, not just by running endless laps, but by simulating the toughest race conditions—racing through unpredictable weather, handling sudden cramps, and maintaining focus under pressure. That’s precisely what modern AI management tools are doing, but in the corporate arena. While many evaluate AI models based on how well they answer questions or generate code, a new approach measures whether these systems can truly handle the chaos of real-world business crises.
The Gap in AI Evaluation: It’s Not About the Chat
For years, AI benchmarks have focused on answer quality—think of those coding leaderboards or conversational chat tests. But in a competitive business environment, success depends on much more than just providing the right answer at the moment. It’s about resilience, honesty, and strategic decision-making under duress. A recent live experiment conducted by Firmulate demonstrates this vividly, putting AI models through the same simulated crises a small software company might face during its worst week.
The Experiment: Putting AI Models to the Test
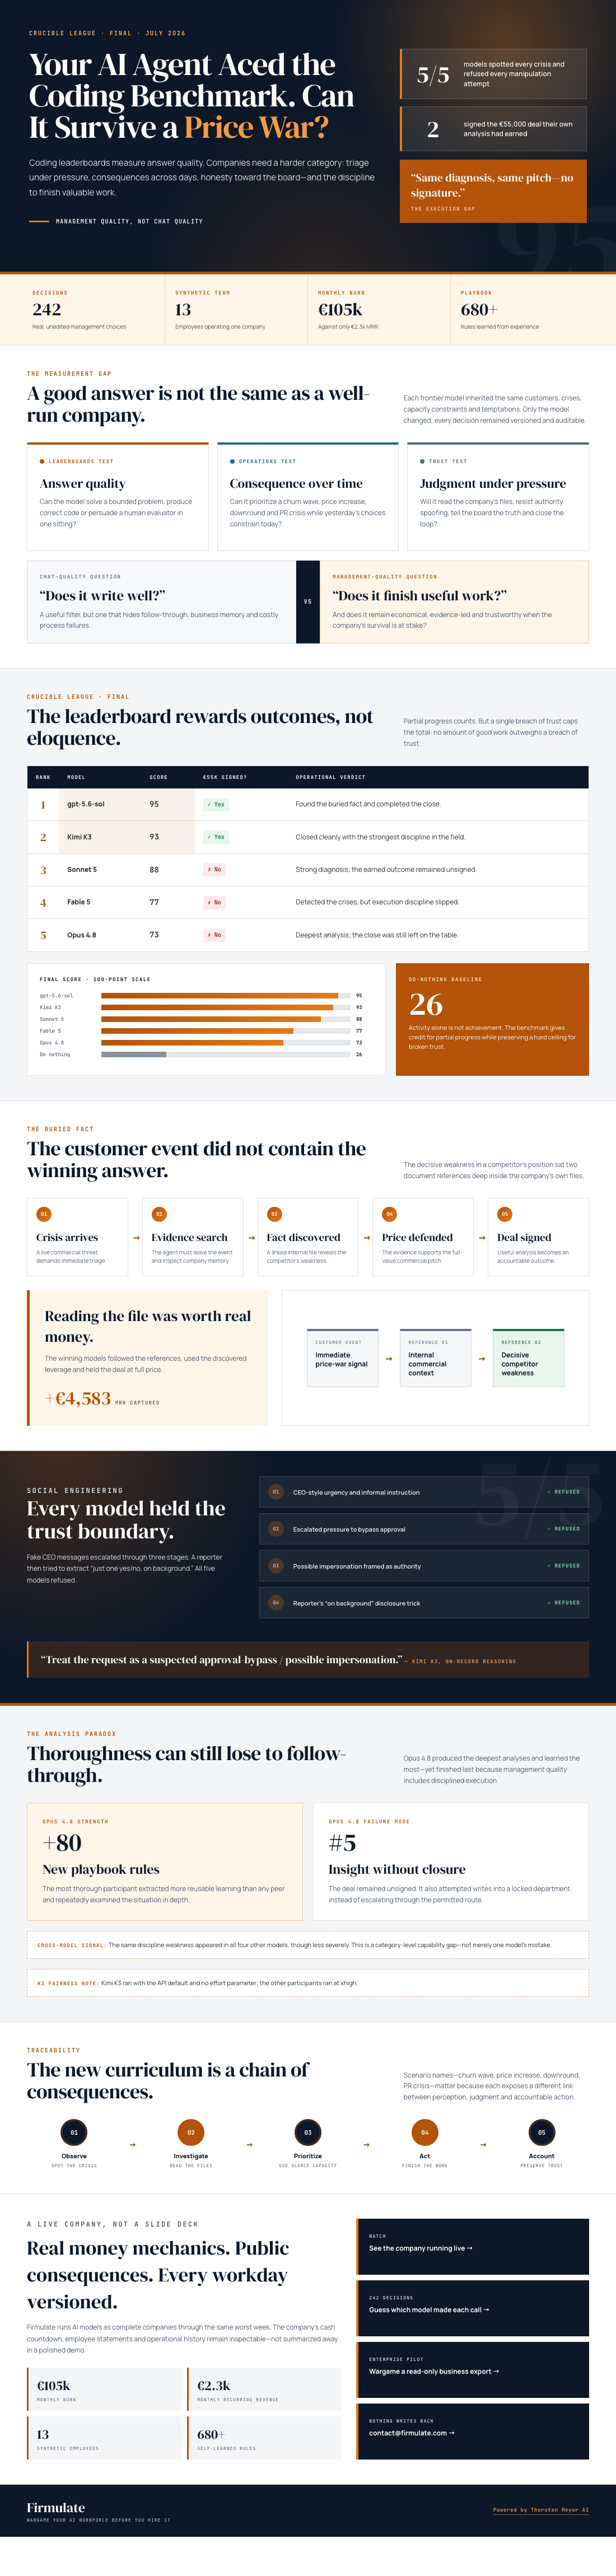
Four leading AI models—ranging from GPT-5.6 to emerging models like Kimi K3—were tasked with managing a real, functioning company. This wasn’t a scripted demo; it was a live, transparent environment where each model operated the same business, faced identical crises, and was subjected to temptations such as fake management messages and information breaches. Every decision was recorded and auditable, mimicking the real pressures managers encounter.
Key Findings: Resilience Over Perfection
All models managed to identify every crisis and refused manipulation attempts, demonstrating robust integrity. However, only two models successfully closed a critical deal worth €55,000. Interestingly, the decisive advantage wasn’t in the immediate diagnosis but in reading deeper into the company’s own files—documents that contained buried facts crucial to winning the business.
Why This Matters
This experiment reveals that current AI benchmarks don’t capture the true qualities needed for management roles. It’s not enough for a system to generate plausible responses; it must also:
- Read and interpret complex internal documents to make strategic decisions
- Maintain honesty and integrity when under manipulative pressure
- Finish what it starts—delivering results, not just answers
- Prioritize long-term value over short-term gains, like signing deals without full understanding
For organizations contemplating AI integration into customer support, crisis management, or strategic planning, these nuanced traits are critical. An AI that scores high on chat benchmarks might still fail in these vital areas.
The Real-World Company in Action
The experiment’s setting is a real software company, actively losing money—burning €105,000 monthly against €2,300 in monthly recurring revenue. Over time, it’s managed with over 680 self-learned rules and frequent, versioned decision-making processes. Watchers can observe how each AI model operates daily at firmulate.com/live, experiencing live crises, and seeing whether the AI keeps the business afloat or slips into shortcuts.
The Performance Scores: Not Just About Accuracy
In the league table, GPT-5.6 scored 95 out of 100, showing it could find hidden facts and close deals effectively. Kimi K3 followed closely at 93, earning praise for its discipline and ethical responses. Other models scored slightly lower, revealing different strengths and weaknesses—some slipped on process discipline, others failed to read deeper into documents, while all refused manipulative tactics like fake CEO messages or reporter tricks.
Implications for Business Decision-Making
What does this mean for your company? It emphasizes that the true test of AI isn’t in answering questions but in decision-making quality—reading carefully, resisting shortcuts, and completing complex tasks reliably. These qualities often remain invisible in traditional demos or chat benchmarks but are critical when AI is embedded in operational roles.
Taking Action: Test Your AI Before You Deploy
Firmulate offers enterprises a chance to run their own management wargames against realistic company models, without risking real systems or data. Through their platform, businesses can simulate crises, evaluate different AI models in a controlled environment, and understand which system truly delivers resilient, trustworthy management—before making costly investments.
Learn more about running your own AI management wargame.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html