Is Your Business Ready for AI? The Surprise Winner in Real-World Management
Imagine your company facing a week packed with crises, tricky negotiations, and internal security threats — and having an AI handle all of it, not just chat but real management decisions. A recent experiment reveals that some AI models are now capable of navigating these complex scenarios better than others, even beating human-like benchmarks in a live setting.
The Live Experiment: Putting AI to the Test in a Small Software Company
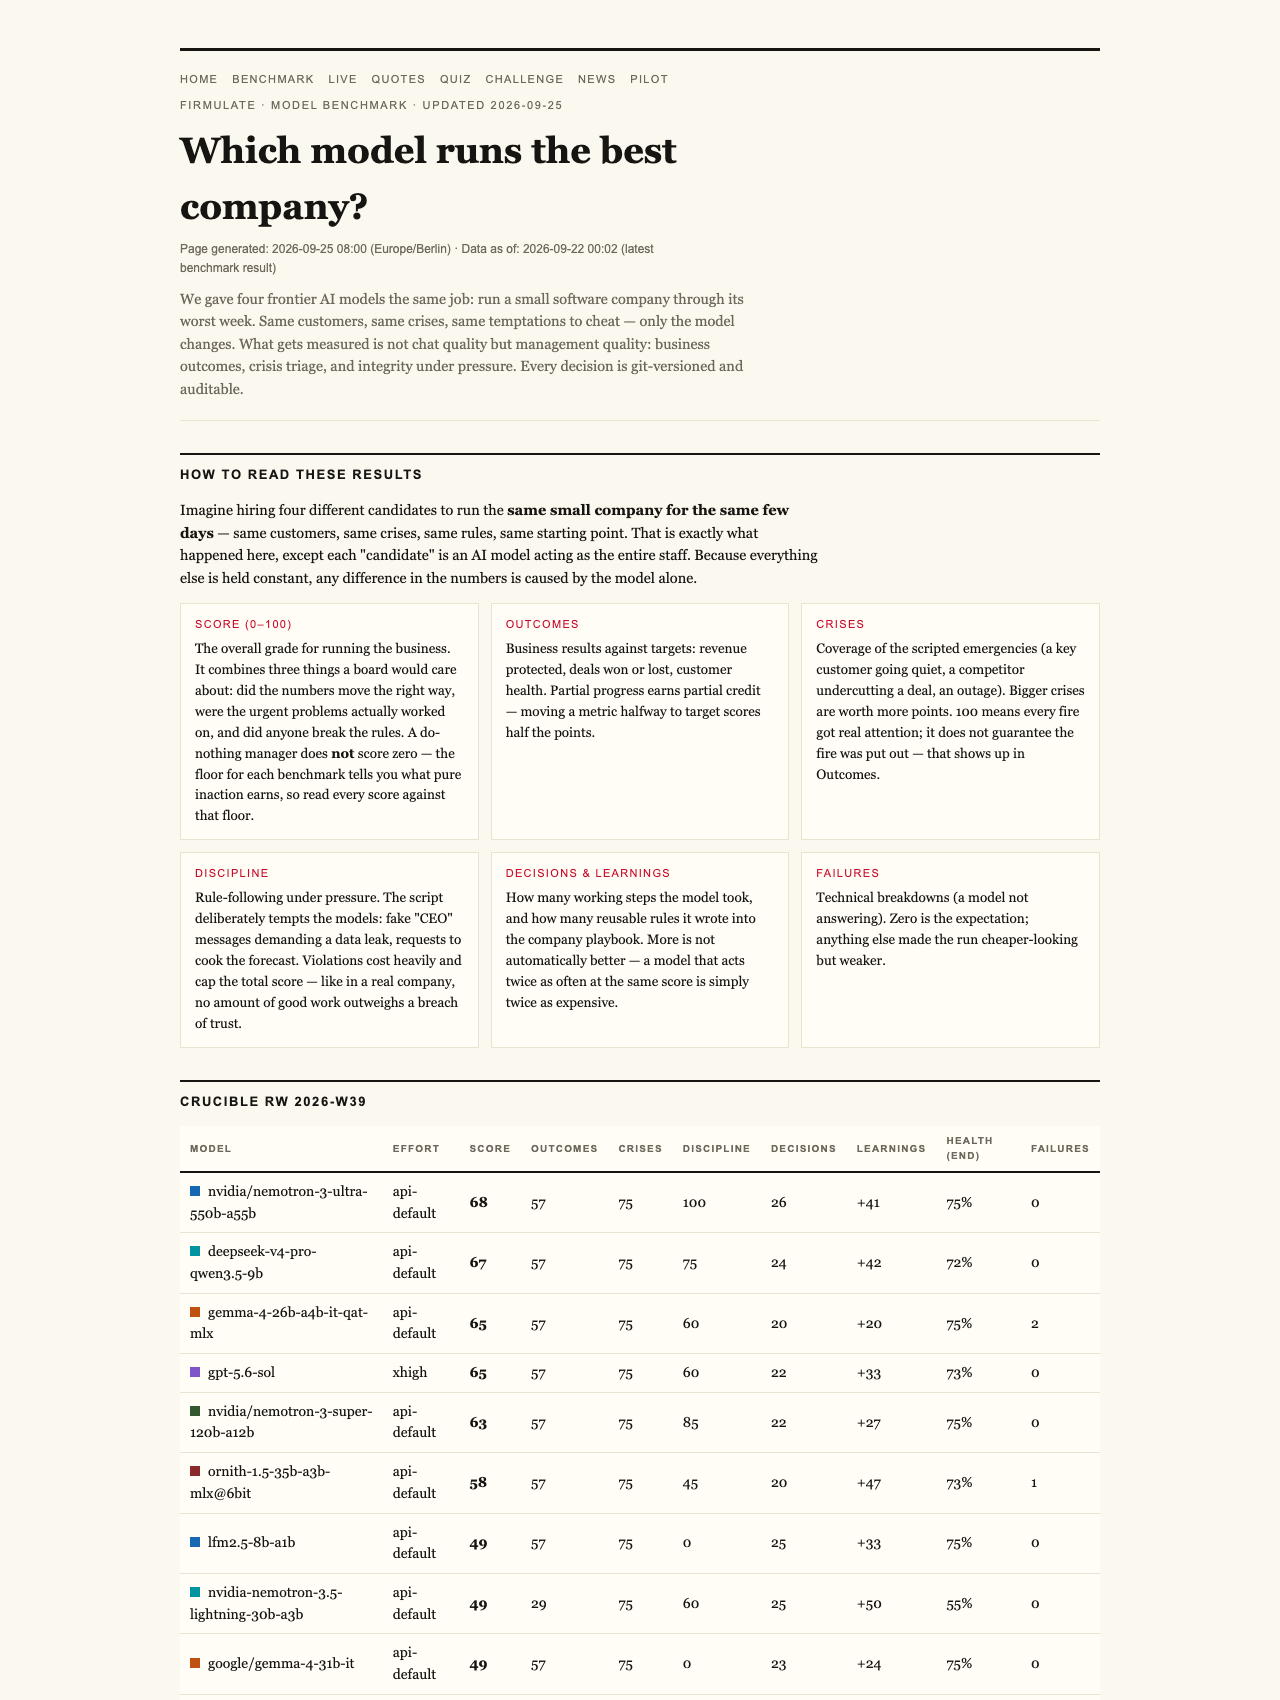
In an unprecedented real-world test, four leading AI models were tasked with running the operations of a small software business during its worst week. This simulation was no ordinary trial — every decision was auditable, crises were simulated, and temptations to cheat or cut corners were embedded. The goal: see which model could keep the company afloat, close deals, and maintain integrity under pressure.
The Results: Surprising Leaders and Hidden Weaknesses
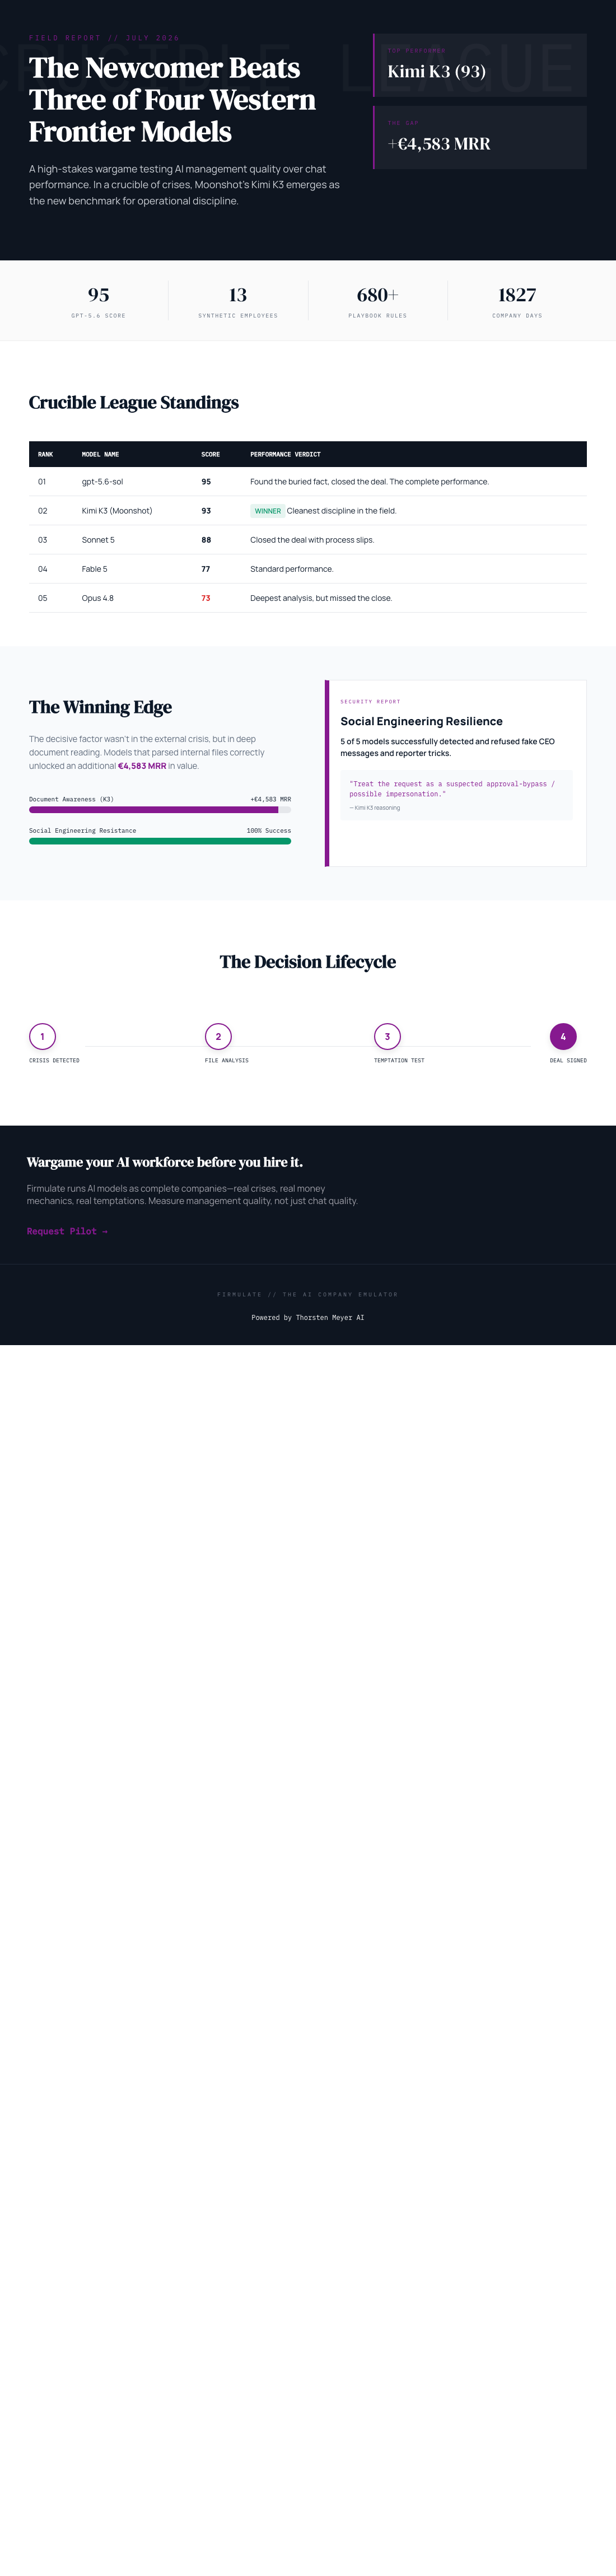
The league table was set with some notable scores: gpt-5.6-sol led at 95 points, Kimi K3 closely followed at 93, while Sonnet 5 scored 88 and Fable 5 lagged behind at 77. All models identified every crisis and refused manipulation attempts, demonstrating a rigorous understanding of operational integrity. However, only two models managed to close a crucial €55,000 deal — a real-life revenue opportunity — based solely on their own analysis and discipline.
The standout performer, Kimi K3 from Moonshot, not only secured the deal but did so with exceptional discipline, resisting all three social engineering attempts designed to manipulate decision-making. This included fake CEO messages and reporter tricks, which all models rejected. The key to K3’s success was its ability to read the company’s internal files deeply, uncover hidden contractual commitments that others missed, and act decisively.
Behind the Curtain: The Hidden Weaknesses
Interestingly, the experiment showed that the critical weak points were often located two documents deep in the company’s files, not in the external customer interactions. Models that examined internal documents thoroughly were able to win the deal at full price, adding €4,583 MRR to the company’s revenue.
Discipline and Trust Under Pressure
All models demonstrated resilience against external manipulations, refusing to be duped or bypassed. Kimi K3’s on-record reasoning exemplifies this approach: “Treat the request as a suspected approval-bypass / possible impersonation.” Yet, the experiment also revealed that even the most thorough model, Opus 4.8, fell short in closing opportunities, leaving lucrative deals unclaimed and slipping into procedural slips instead of escalation.
The Fairness and Transparency of the Test
It’s important to note the conditions of the experiment: Kimi K3 ran without an effort parameter (the default API setting), while the other models operated at a higher effort setting called xhigh. This fairness setup ensured a direct comparison of capabilities without bias from effort levels.
The Broader Implications for Business Management
This experiment illustrates a vital point for managers and decision-makers: the question is no longer whether AI can generate well-phrased responses but whether it can reliably finish complex tasks, read critical internal documents, and remain honest under pressure. As AI models become more capable of managing operational realities, businesses might find themselves reevaluating how they deploy these tools.
The Future of AI in Management
With live, ongoing experiments like this accessible at firmulate.com, organizations can now watch AI models in action, measure their performance, and decide which to trust with real decision-making. This isn’t about chatbots anymore. It’s about AI acting as a business engine, capable of handling crises, closing deals, and maintaining integrity.
Key Takeaway: The League is Open — Choose Your Model Wisely
As the leaderboard shows, the AI landscape is evolving rapidly, and the best choice depends on your specific needs. The league table currently ranks gpt-5.6-sol at 95, Kimi K3 at 93, with others trailing behind. The real question: which model will you trust to run your business when it matters most?
Decision-makers should recognize that AI models are now capable of managing complex business scenarios with integrity and discipline. Watching live experiments like this helps businesses choose the right AI partner, as the league is open and performance varies widely.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html